-
DataHoarder
slowbeardigger:matrix.org: I have one extra testcase on
git.gammaspectra.live/P2Pool/consen…o/curve25519/montgomery_test.go#L25 if you want to check compliance (plus other tests)
-
DataHoarder
-
br-m
<slowbeardigger:matrix.org> Thank you! will check
-
br-m
<slowbeardigger:matrix.org> will check after my coffee is ready
-
DataHoarder
for reference the Go code is no-alloc as well, and runs at 2466 ns/op 0 B/op 0 allocs/op on a ECO-mode low-throttled 9950X3D single-core
-
DataHoarder
I also have a batch unclamped scalar mult api, but that's not alloc-free (some slices that are ephemeral still get tracked as allocs, even when they will most of the time land on stack)
-
br-m
<slowbeardigger:matrix.org> That’s really interesting.
-
br-m
<slowbeardigger:matrix.org> Could you pls share the same result with -cpu=1 or GOMAXPROCS=1? if you get a chance ofc
-
DataHoarder
right, that test is trying to do parallel, my bad. it shouldn't need to be, one sec :D
-
DataHoarder
I never updated this code to use the new nicer single-core methods
-
br-m
<slowbeardigger:matrix.org> DataHoarder: no problemou
-
br-m
<slowbeardigger:matrix.org> I was wondering because 2466 ns/op would be wild for single-call latency
-
DataHoarder
it is wild :)
-
DataHoarder
I was currently profiling it cause it looked fast
-
DataHoarder
BenchmarkX25519ScalarMult-24 198880 30020 ns/op 0 B/op 0 allocs/op
-
DataHoarder
-24 but it's running on one core
-
br-m
<slowbeardigger:matrix.org> -24 suffix is just the GOMAXPROCS setting?
-
br-m
<slowbeardigger:matrix.org> about the same ballpark as my x86 BMI2+ADX result (~28.9 us on a GitHub runner)
-
br-m
<slowbeardigger:matrix.org> fucking impresive
-
DataHoarder
I did optimize the field elements a bit :)
-
br-m
<slowbeardigger:matrix.org> legend
-
DataHoarder
I run a fork on
git.gammaspectra.live/P2Pool/edwards25519 and there is asm for field mul / field square
-
DataHoarder
but field inversion / specialized types for x^((p-5)/8) or x^((p-3)/8) were made
-
br-m
<slowbeardigger:matrix.org> DataHoarder: AHHHHHH
-
DataHoarder
and for X25519 I have a method to do x * 121666 specifically
-
DataHoarder
no BMI2 or ADX though!
-
br-m
<slowbeardigger:matrix.org> no BMI2/ADX and still ~30 us is damn good
-
br-m
<slowbeardigger:matrix.org> would love a same-host carrot25519 run on that 9950X3D 👀
-
br-m
<slowbeardigger:matrix.org> just for the numbers 👀 👀 👀 👀 👀
-
DataHoarder
you can run mine :D
-
br-m
<slowbeardigger:matrix.org> will do
-
DataHoarder
-
DataHoarder
also, 9900X3D, not 9950X3D, I misspoke :P
-
br-m
<slowbeardigger:matrix.org> still a beast
-
DataHoarder
your carrot25519_mul_base has an equivalent on mine, constant time and vartime too:
-
DataHoarder[m]
BenchmarkX25519ScalarBaseMult/Constant 496590 11425 ns/op 0 B/op 0 allocs/op
-
DataHoarder[m]
BenchmarkX25519ScalarBaseMult/VarTime 698203 8371 ns/op 0 B/op 0 allocs/op
-
DataHoarder[m]
in my case it's faster to do the scalar mult and encode to Montgomery :)
-
DataHoarder[m]
for Carrot specific environment that is acceptable when producing them
-
br-m
<slowbeardigger:matrix.org> Agreed that makes sense for carrot key gen
-
br-m
<slowbeardigger:matrix.org> Probably best as a separate scalar fast path? While the mul keeps unchanged
-
DataHoarder[m]
vartime allows precalc stuff yes :)
-
br-m
<slowbeardigger:matrix.org> Ran your commit on my M1 base
-
br-m
<slowbeardigger:matrix.org> 44.16 us for arbitrary point
-
DataHoarder
-
br-m
<slowbeardigger:matrix.org> Your field ops is awesome
-
br-m
<slowbeardigger:matrix.org> My laptop got stupid running some.benchmark
-
br-m
<slowbeardigger:matrix.org> Had to move to my phone here
-
br-m
<jpk68:matrix.org> Good thing isogenies exist, or else we'd just be throwing all of this curve stuff out the window
-
DataHoarder
don't run every benchmark there lol, just the ones on that specific subpath
-
br-m
<slowbeardigger:matrix.org> Too late
-
br-m
<slowbeardigger:matrix.org> laptop goes brrrr
-
DataHoarder
there's some benchmark or tests on mining if you keep pulling deps, so at some point you are mining lol
-
br-m
<slowbeardigger:matrix.org> ill just let it be
-
br-m
<slowbeardigger:matrix.org> turning on my backup laptop
-
DataHoarder
the code you posted still performs faster, ofc, all hail slow compilers
-
br-m
<slowbeardigger:matrix.org> still, your Go numbers are seriously good, and now I have a base fast path to investigate 👀
-
DataHoarder
see VarTimeScalarMultPrecomputed and ScalarMultPrecomputed on that forked repo, it's where I placed that + tables that get computed
-
br-m
<slowbeardigger:matrix.org> noted, will check it out sounds like exactly the direction I need 👀
-
DataHoarder
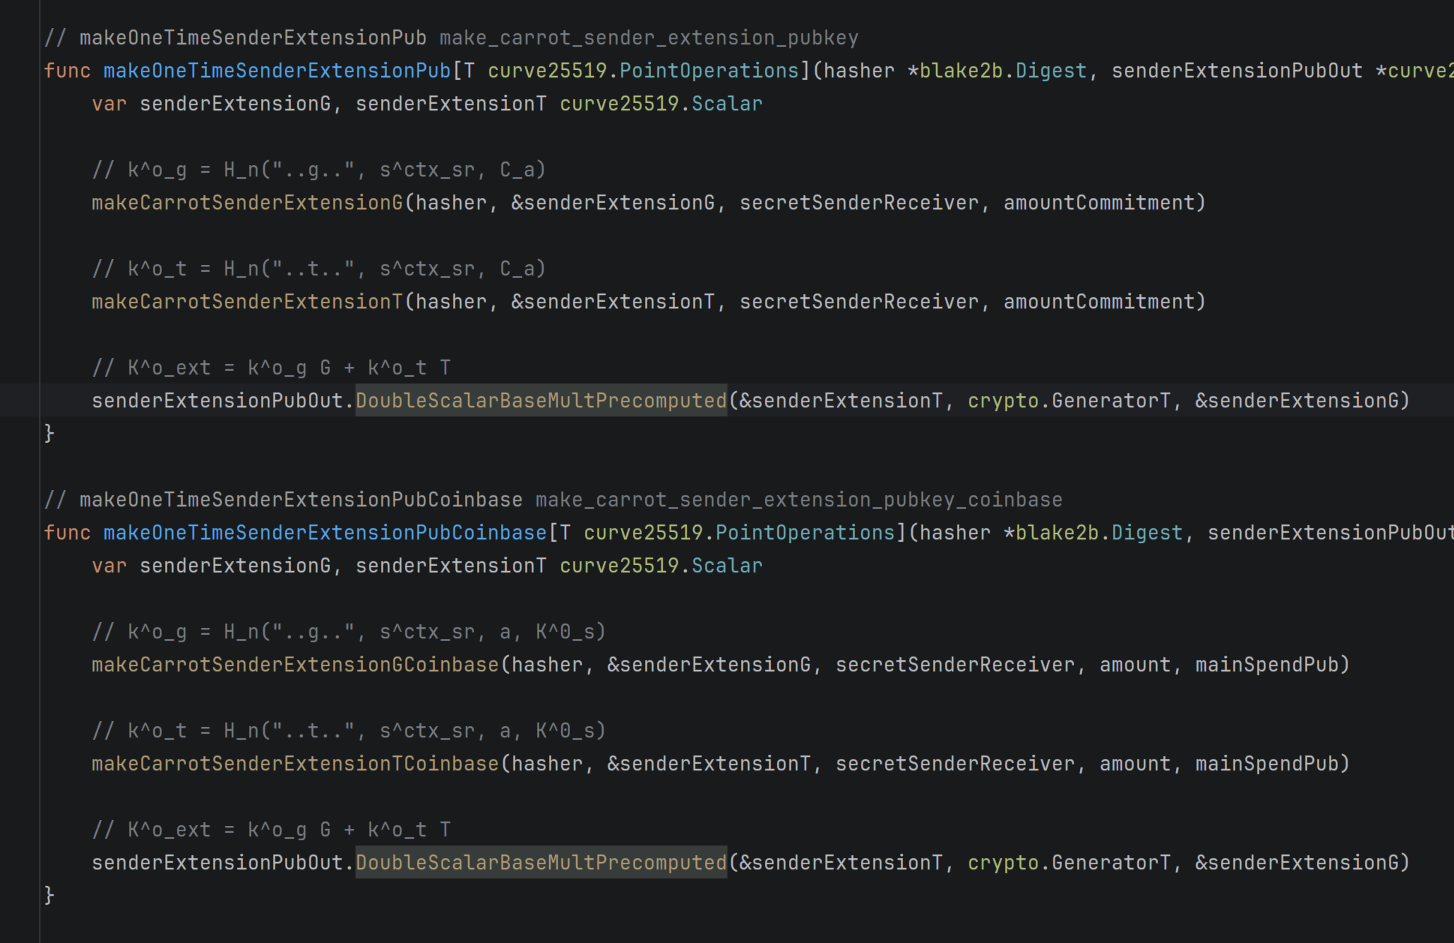
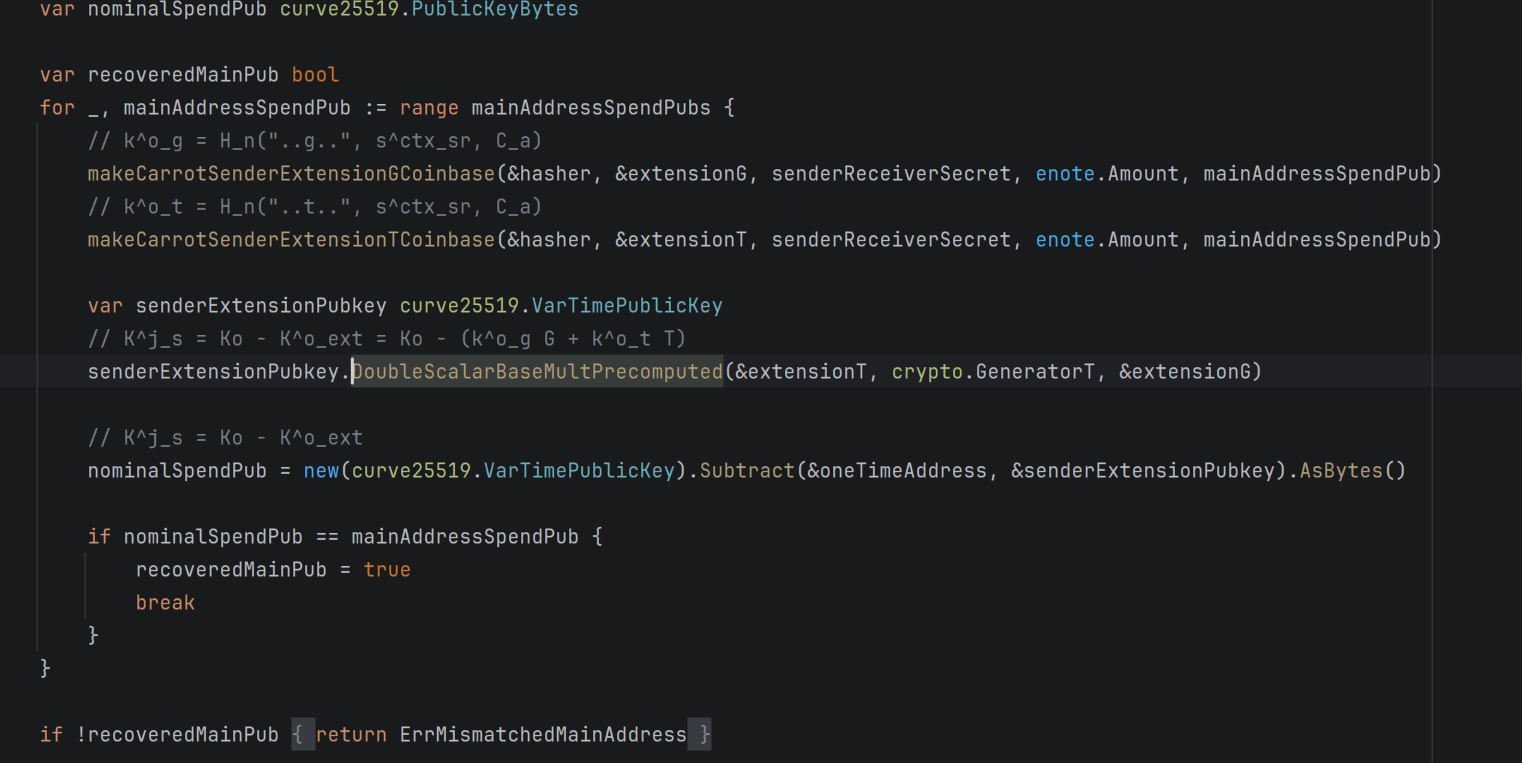
though most of the speedups I get along the code is due to having DoubleScalarMult or DoubleScalarBaseMult specific paths, which happens a lot in monero (each also has a VarTime option), specially when I can precompute the two bases (like for monero commitments or other areas with monero specific generators)
-
br-m
<slowbeardigger:matrix.org> you’re optimizing the actual monero equations rather than isolated scalar mult 👀
-
DataHoarder
-
DataHoarder
stuff like this
-
DataHoarder
where one generator is G, other is T
-
DataHoarder
so both are public and can be precomputed
-
br-m
<slowbeardigger:matrix.org> Seems like i wont work tomorrow focusing on this
-
DataHoarder
-
DataHoarder
sadly a lot of the new stuff ends up with a variable amount of chained scalar mults so I just feed everything to my MultiScalarMult :) but maybe I should add some mixed method there that has a precalc section beforehand as that would be cheaper
-
br-m
<slowbeardigger:matrix.org> that feels like the next move
-
DataHoarder
then there's some batch specific optimizations that work quite well on p2pool, monero had some added my kayaba
-
DataHoarder
by*
-
DataHoarder
specially when we calculate 700 or so outputs we can do a batched invert when converting to bytes :)
-
DataHoarder
but tbh for a bunch of stuff done, whatever comes out of
github.com/mit-plv/fiat-crypto is what gets used :)
-
DataHoarder
with maybe some
github.com/mmcloughlin/addchain thrown around to generate addchains for specific field exponentation calls usually
-
br-m
<slowbeardigger:matrix.org> Will catch up with you later > <DataHoarder> then there's some batch specific optimizations that work quite well on p2pool, monero had some added my kayaba
-
br-m
<slowbeardigger:matrix.org> Been nonstop